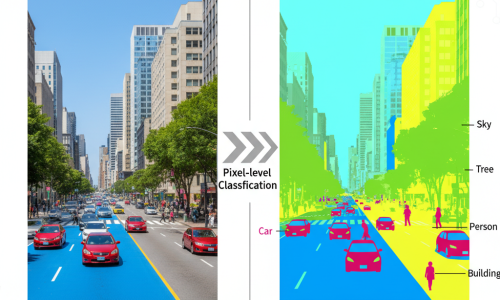
Semantic segmentation is an image annotation technique that assigns a class label to every pixel in an image. It helps computer vision models distinguish regions such as roads, vehicles, pedestrians, buildings, and vegetation at the pixel level.
AnnotationWorld provides data annotation services for AI and machine learning projects. Semantic segmentation workflows can be tailored to project-specific labeling guidelines, target classes, image types, and dataset requirements.
How Semantic Segmentation Works
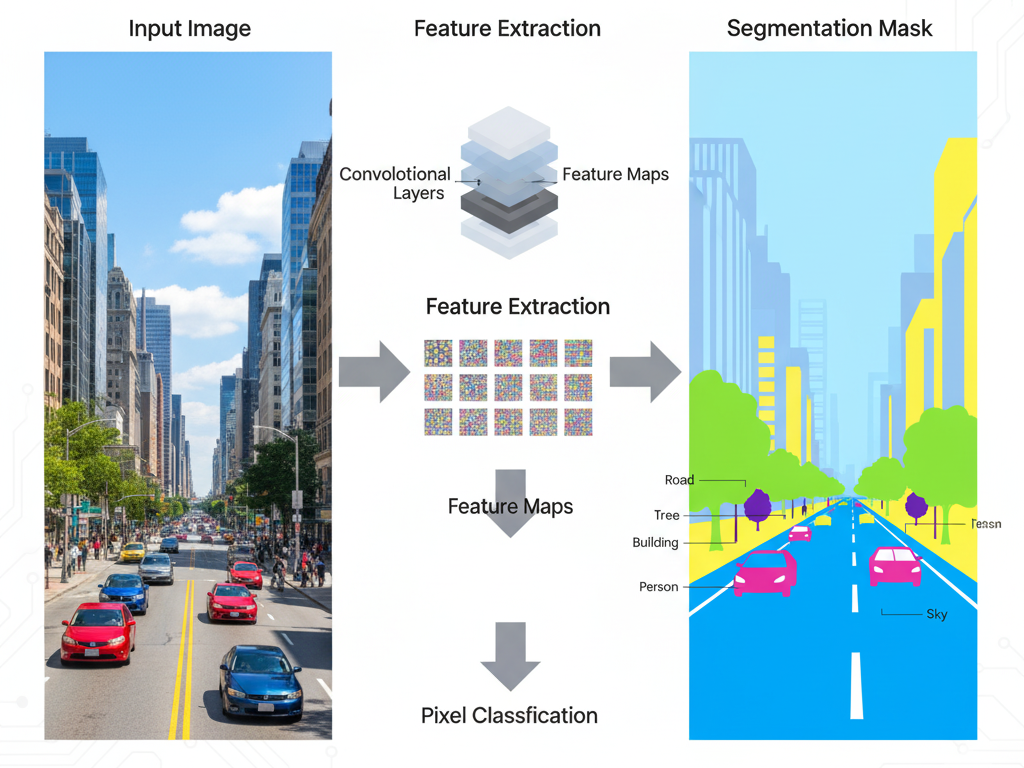
Data Preparation: The process begins with annotated datasets where every pixel is labeled with its class (e.g., sky, car, road).
Feature Extraction: Deep neural networks (like CNNs or Vision Transformers) extract spatial and contextual features from the image.
Pixel Classification: Each pixel is classified based on its extracted features and surrounding context.
Upsampling / Decoding: The network reconstructs pixel-level predictions using upsampling layers (e.g., in U-Net, SegNet, or DeepLab architectures).
Mask Generation: A color-coded segmentation mask is generated, overlaying class labels onto the original image.
Post-Processing: Techniques like Conditional Random Fields (CRFs) or edge refinement are used to sharpen object boundaries.
Model Optimization: The model is fine-tuned using metrics like Intersection over Union (IoU) and Pixel Accuracy to improve segmentation quality.
Types of Segmentation
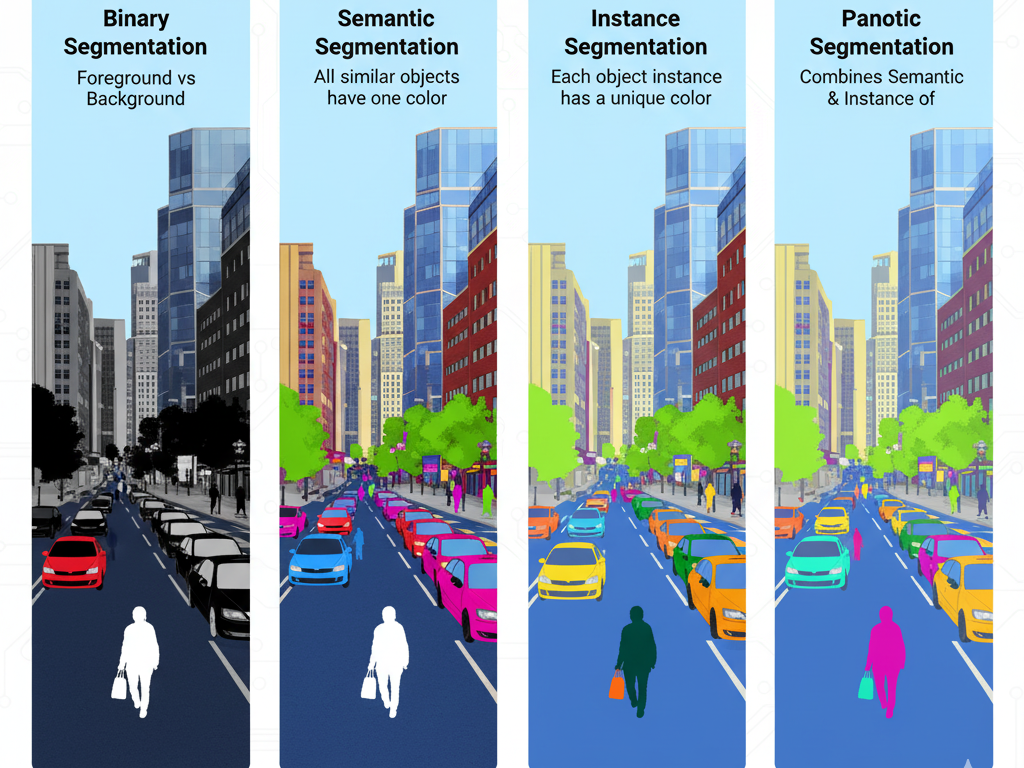
Semantic Segmentation:
- Assigns a class label to each pixel.
Instance Segmentation:
- Identifies each object instance separately within the same class.
Panoptic Segmentation:
- A hybrid of semantic and instance segmentation.
Binary Segmentation:
- Simplest form — classifies pixels into two categories (e.g., foreground vs background).
3D Segmentation:
- Extends semantic segmentation into 3D environments (e.g., LiDAR point clouds).
Applications
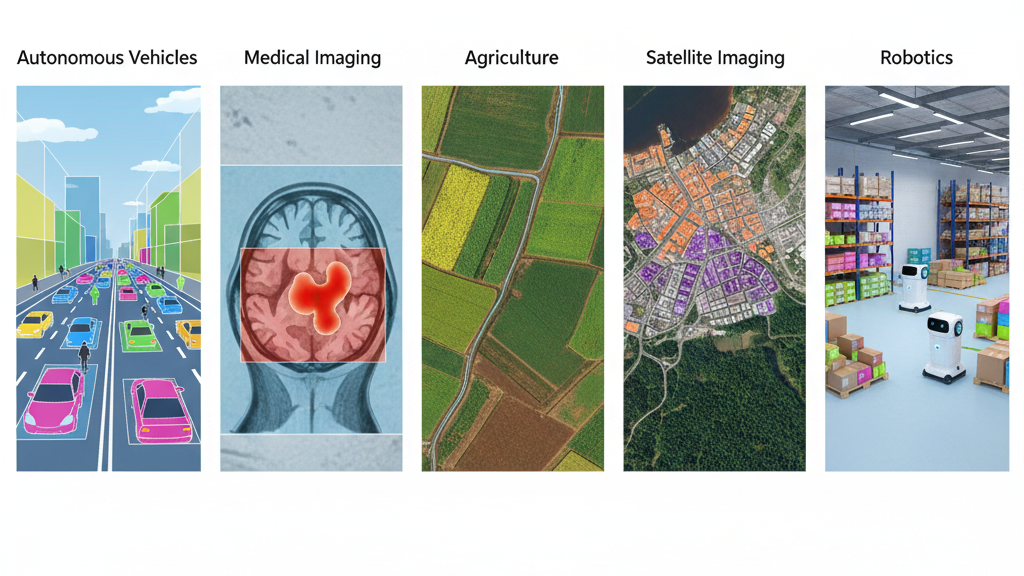
Autonomous Vehicles: Understanding roads, lanes, pedestrians, and obstacles.
Medical Imaging: Identifying tissues, tumors, or organs at the pixel level.
Agriculture: Segmenting crops, soil, and weeds for precision farming.
Aerial & Satellite Imagery: Land-use classification, forest monitoring, and urban mapping.
Robotics: Scene understanding for navigation and manipulation.
AR/VR: Separating background and foreground objects for immersive environments.
Quality Control in Semantic Segmentation
Accurate pixel-level labels help create useful training datasets. Quality checks may include:
- Following consistent class definitions and annotation guidelines.
- Reviewing object boundaries and small image regions.
- Checking missing pixels, mislabeled areas, and class inconsistencies.
- Applying consistent rules to overlapping or partially visible objects.
- Validating masks against the required annotation format.
The review process should reflect the dataset’s complexity and the project’s requirements.
Semantic Segmentation Services by AnnotationWorld
AnnotationWorld provides data annotation services for AI and machine learning projects. Semantic segmentation requirements can be defined around target classes, image volume, annotation guidelines, quality criteria, and preferred output formats.
Contact AnnotationWorld to discuss your dataset requirements and determine a suitable annotation workflow.
Frequently Asked Questions
What is semantic segmentation in computer vision?
Semantic segmentation assigns a category label to every pixel in an image, helping AI models identify and distinguish different regions.
What is the difference between semantic and instance segmentation?
Semantic segmentation labels pixels by class, while instance segmentation distinguishes individual objects belonging to the same class.
Which metrics are used to evaluate semantic segmentation?
Common metrics include Intersection over Union (IoU), mean IoU, and pixel accuracy. The appropriate metric depends on the task and dataset.
Which industries use semantic segmentation?
Applications include autonomous driving, medical imaging, agriculture, satellite imagery, robotics, and augmented reality.
When should I use semantic segmentation instead of bounding boxes?
Semantic segmentation is useful when a task requires pixel-level region boundaries. Bounding boxes are often sufficient when the goal is to locate objects using rectangles.